
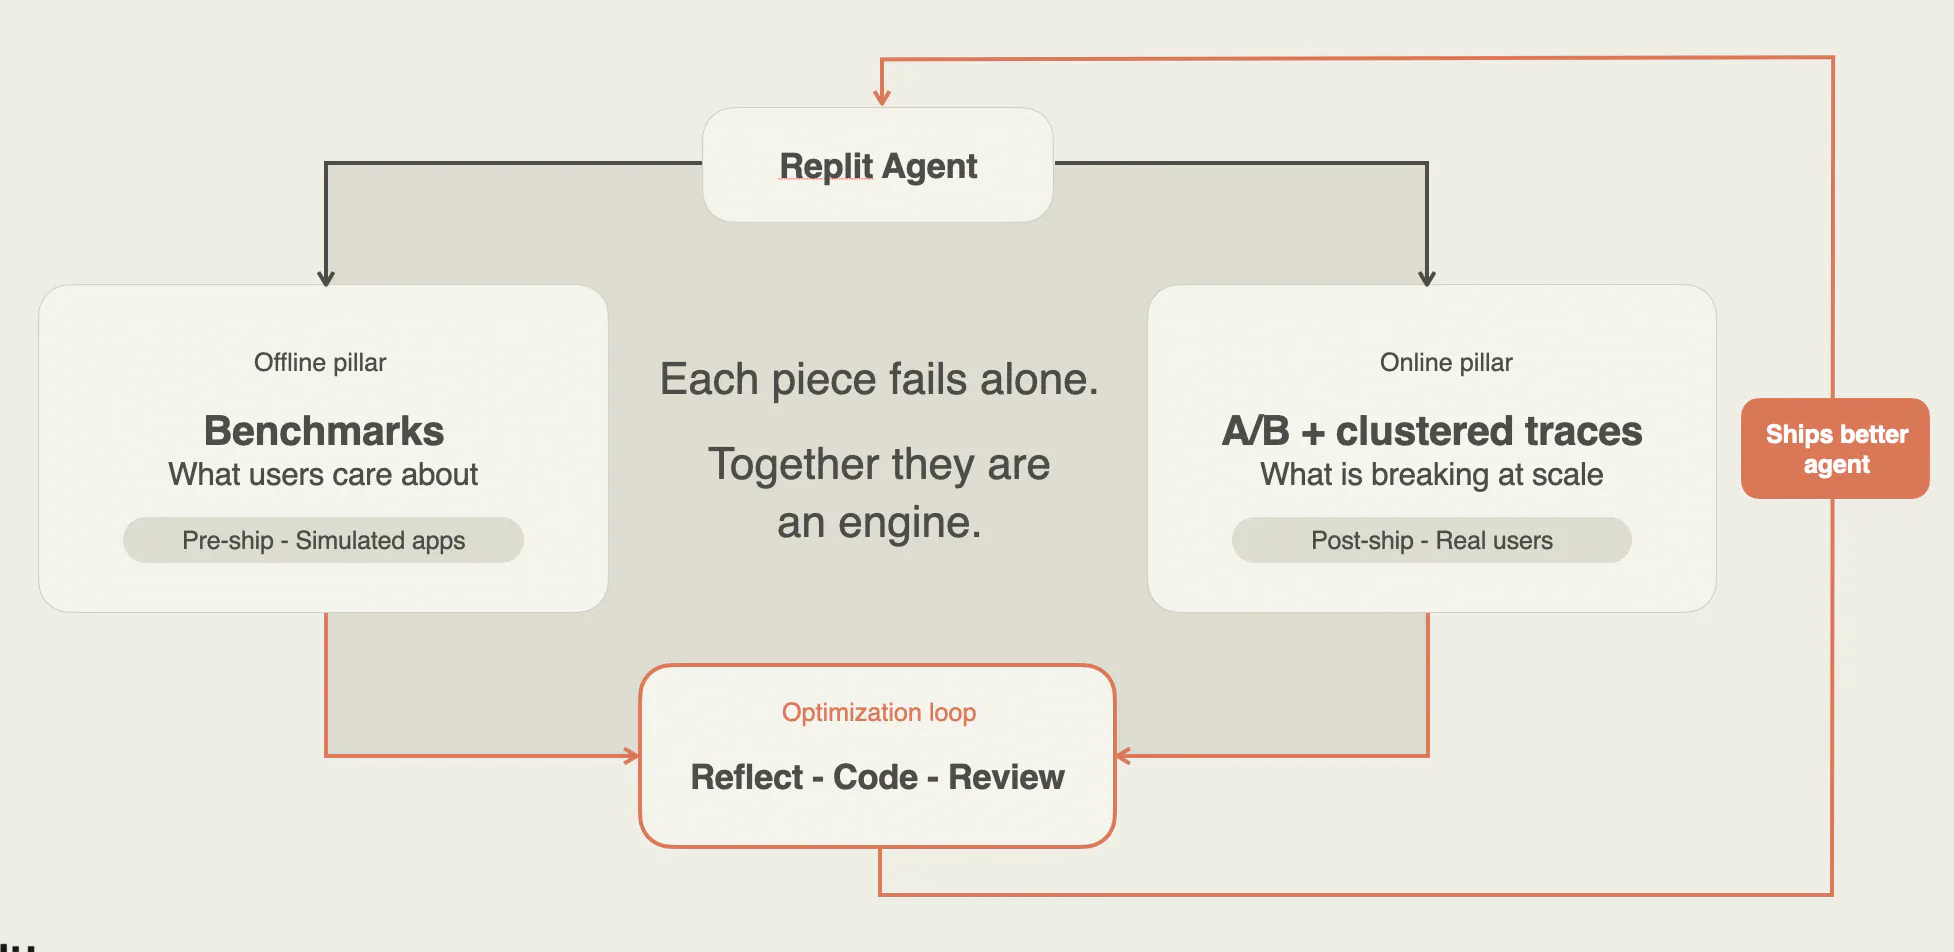
Closing the loop: Evaluating and improving Replit Agent at scale
A benchmark score can’t tell the whole story. How we combine app testing, A/B experiments, and failure analysis to make Replit Agent better.
A benchmark score can’t tell the whole story. How we combine app testing, A/B experiments, and failure analysis to make Replit Agent better.
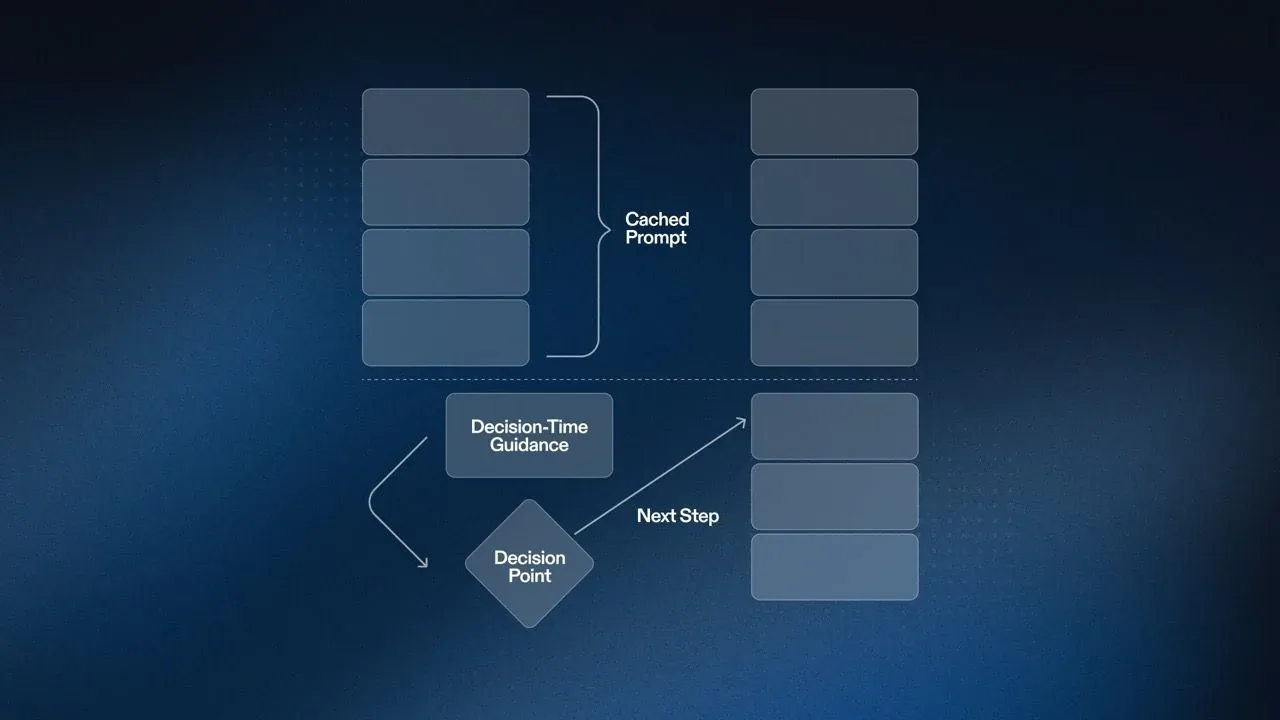
Replit Agent stays reliable through decision-time guidance—injecting situational instructions at key moments rather than front-loading all rules.