
ViBench 2.0: A Benchmark for Long-Horizon Software Building
ViBench 2.0 tests whether AI agents can build a whole product one feature at a time. It joins the Specialized Intelligence Index from Fireworks.
ViBench 2.0 tests whether AI agents can build a whole product one feature at a time. It joins the Specialized Intelligence Index from Fireworks.
Model routers are everywhere right now, but they have a fundamental limitation. No matter if based on advanced heuristics or a small model that reads each turn and picks which LLM to use, a router will always be less capable than the model it’s choosing for. Replit Agent lets the model decide instead.
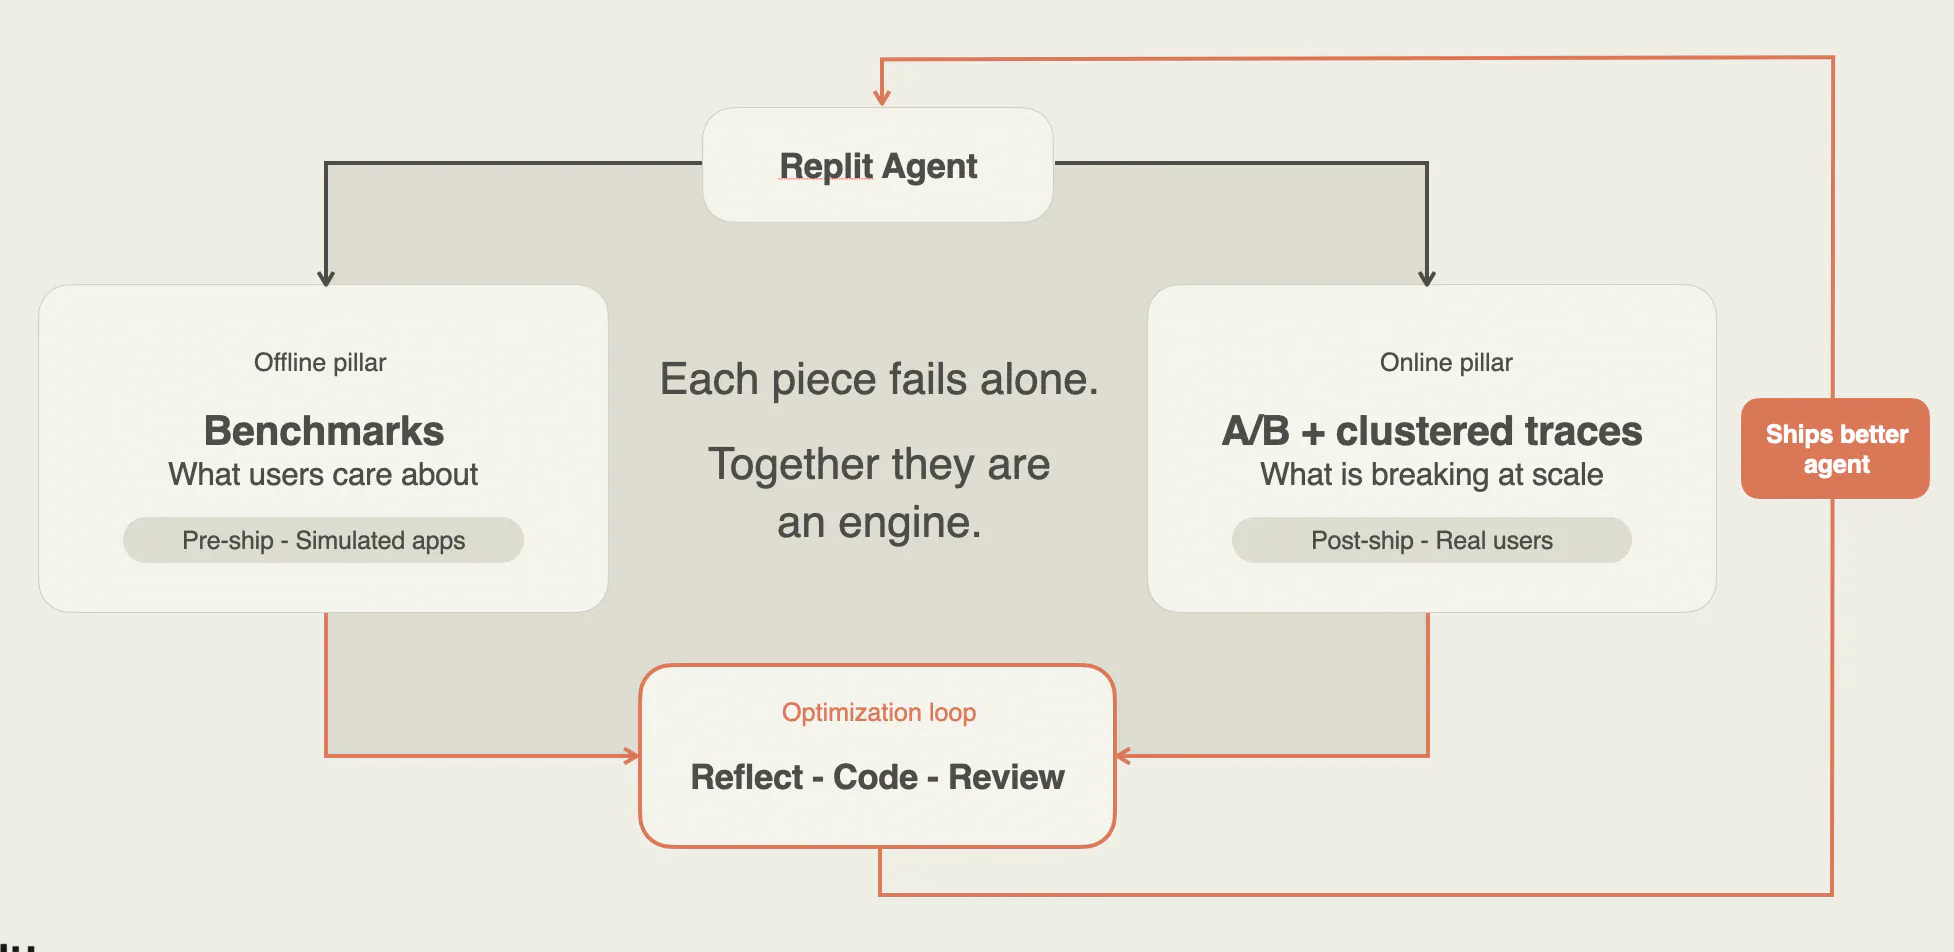
A benchmark score can’t tell the whole story. How we combine app testing, A/B experiments, and failure analysis to make Replit Agent better.