
ViBench 2.0: A Benchmark for Long-Horizon Software Building
ViBench 2.0 tests whether AI agents can build a whole product one feature at a time. It joins the Specialized Intelligence Index from Fireworks.
ViBench 2.0 tests whether AI agents can build a whole product one feature at a time. It joins the Specialized Intelligence Index from Fireworks.
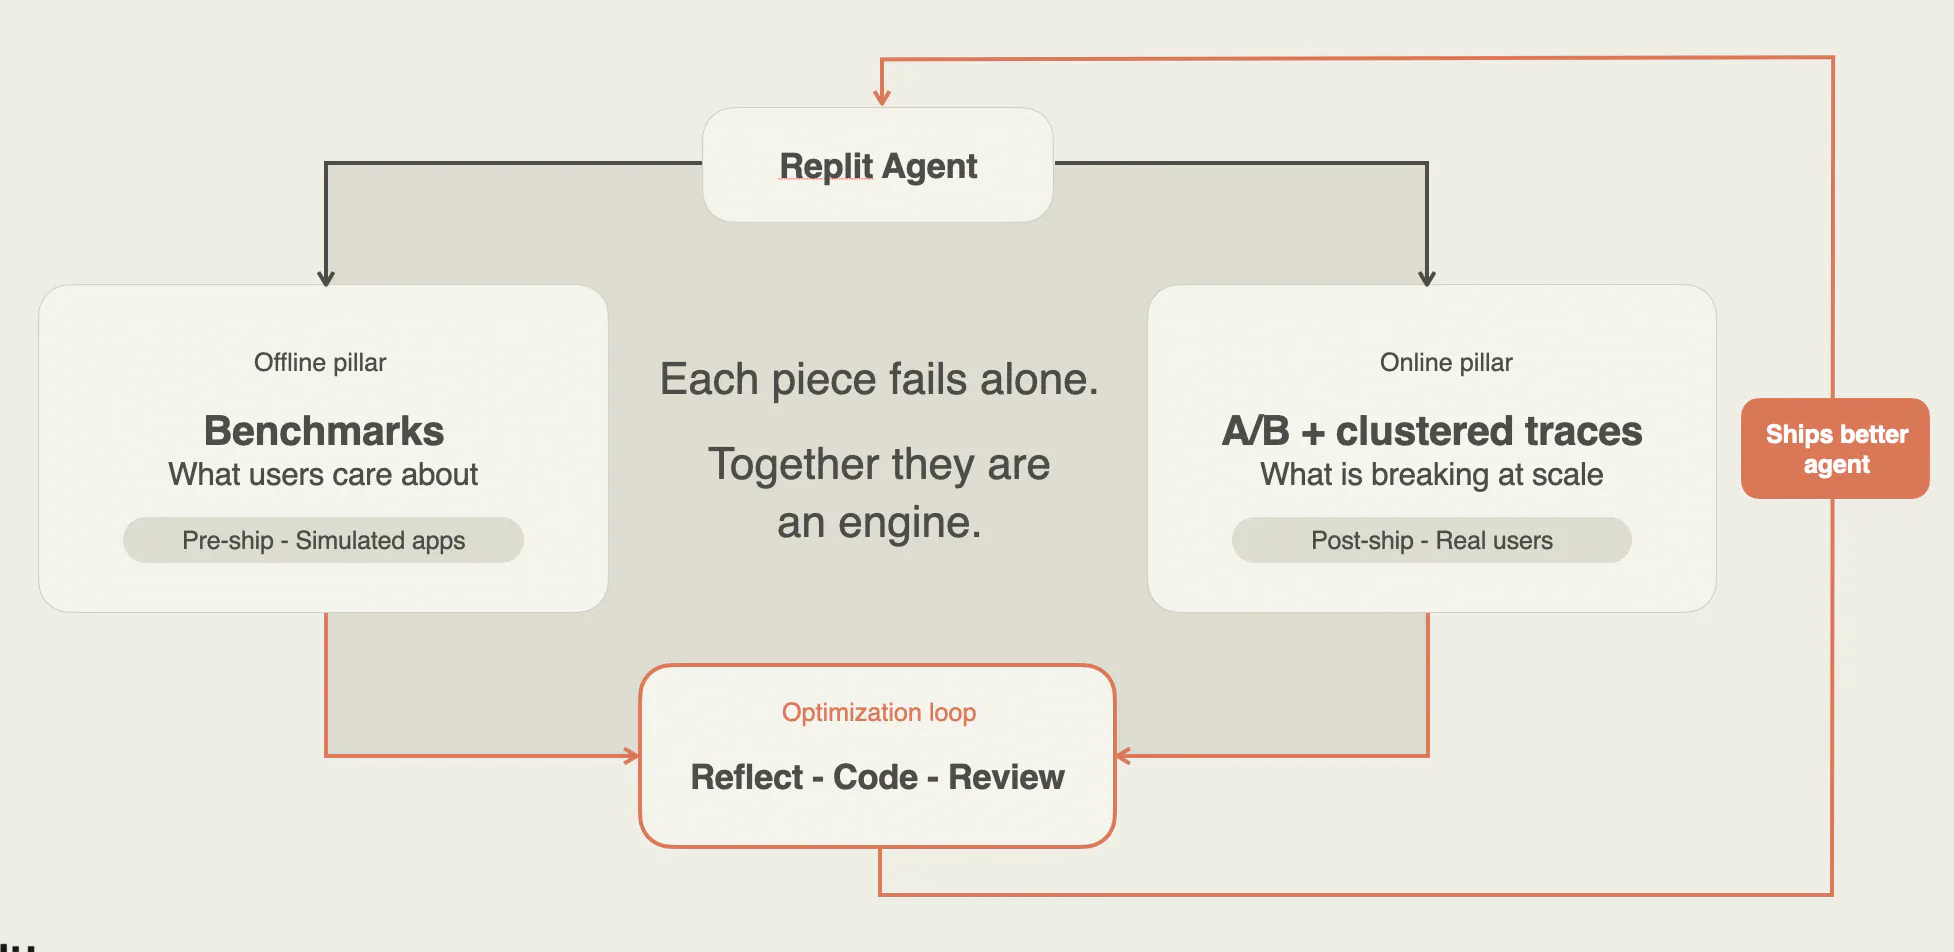
A benchmark score can’t tell the whole story. How we combine app testing, A/B experiments, and failure analysis to make Replit Agent better.
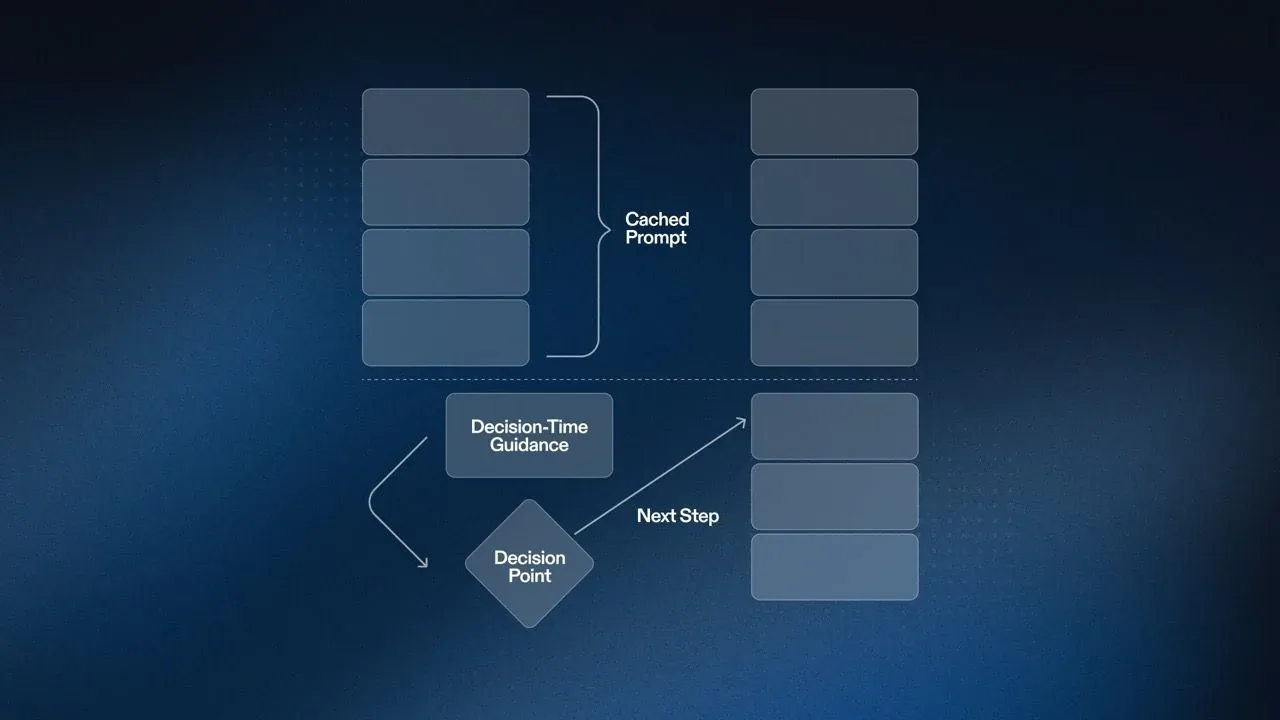
Replit Agent stays reliable through decision-time guidance—injecting situational instructions at key moments rather than front-loading all rules.
An app can look finished and still fail when you click it. How Agent 3 combines code execution and browser testing to check its own work.